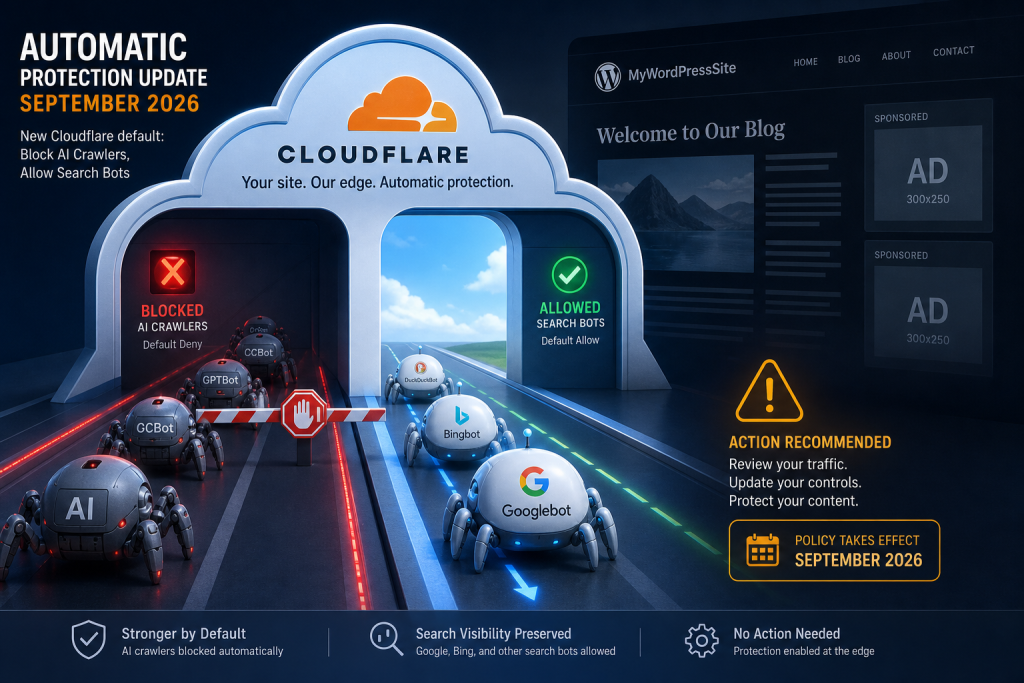
From September 15, 2026, Cloudflare blocks Training and Agent crawlers by default on pages that display ads. Search crawlers stay allowed. The change applies to new customers, new sites added by existing customers, and all existing free customers. Cloudflare announced it on July 1. The default does not flip that day. It flips on September 15.
If you put a WordPress site behind Cloudflare’s free plan years ago and never opened the bot screen again, this is now your setting. A default is a decision someone else makes for you. This one lands in three weeks on sites whose owners did nothing.
50.6 percent is the case they are making
Cloudflare’s early June 2026 network figures, reported with the July 1 announcement, put training-related crawlers at 50.6% against 10.7% from search bots. That is the number they want you to remember. Training bots eat bandwidth. Search bots, in their telling, still send people.
We do not need to argue with the traffic mix. The mix is why a CDN with a huge free tier is rewriting the default. The argument we have is about who that rewrite is for.
Search stays. Training and Agent do not
Cloudflare splits crawlers three ways: Search, Training, and Agent. On pages that show ads, the new default lets Search through and stops the other two.
Training is the scrape for model weights. Agent is the crawler that fetches a page so a model can answer a person, or act. Putting those two in the same blocked bucket is the part that does not survive contact with a store or a service business.
Mixed-use crawlers get the same treatment. If a vendor keeps one bot for search, training, and agent work, Cloudflare treats it as the blocked categories on ad pages. Search-only crawlers that stay search-only still pass.
The rule is scoped to pages that display ads. That sounds precise until you remember how many WordPress sites run an ad plugin, a leftover AdSense tag, or an affiliate unit on a page that is otherwise a product or a services pitch. The trigger is ads on the page, not “you are a publisher.”
Pay Per Crawl is becoming Pay Per Use
In the same announcement, Cloudflare is moving Pay Per Crawl toward Pay Per Use. Publishers get paid when their content shapes an AI answer, not when a bot fetches a URL. Ceramic.ai and You.com are the first partners. There is no firm date for broad availability.
That is a publisher product. It assumes the interesting question is how a media site gets paid when a model uses the article. Fine. A plumber’s site, a WooCommerce catalog, and an agency portfolio are not waiting on Ceramic.ai. Those sites want the assistant to know they exist.
Right for a publisher. Wrong for a store
If you sell pageviews, blocking Training is probably right. Training crawlers do not click ads. They do not subscribe. They copy the thing you monetize and leave. Agent visits that never render an impression sit in the same bucket for a publisher: cost without a slot filled.
If you sell a product, a booking, or a service, the same default is probably wrong. The person who used to Google you now asks an assistant. That assistant has to fetch something. In Cloudflare’s taxonomy, that fetch is Agent, and Agent is blocked next to Training.
We would rather say that plainly than split the difference. Ad-supported publishers should likely leave the new default on. Businesses, stores, and service providers should go look at the toggle and, in most cases, let Agent through.
A customer’s assistant is not a scraper
The mixed-use crawler problem is real. Some bots train. Some bots shop. Some bots do both, and vendors are not always honest about which. Cloudflare’s three-way split is a serious attempt at a taxonomy. We would rather have Search, Training, and Agent than a single “AI bots” kill switch.
It still does not map cleanly onto business models. A publisher’s loss is a training scrape. A store’s loss is a prospective customer whose assistant never read the shipping page. Those are not the same event wearing different labels. Blocking Agent alongside Training treats them as if they were.
That is the take. Not “AI is good” or “AI is theft.” The category is too coarse for the sites most WordPress agencies actually run.
Look at the setting before September 15
Do not inherit this. Open the Cloudflare dashboard, find the AI crawler controls, and treat Training and Agent as two decisions. Write down why you flipped each one. Owners can always let a blocked category back in. The starting position is what changed.
Agencies: this is a client-site pass, not a blog post to forward. Free-plan sites you stood up in 2023 are in the blast radius. Existing customers who add a new site get the new default on that site, even if the old ones were left alone.
Search can stay allowed. That is the one Cloudflare is not flipping. Training is the one most commercial sites can keep blocked without losing a buyer. Agent is the one to stare at.
If a leftover ad unit is what would trigger the default on a page that is not actually a media property, fix that too. The policy keys off ads on the page, not off how you think of yourself.
The answer surface you still control
Whatever you decide about crawlers, you still have the conversation that happens on your own site. PressBot’s Knowledge Base and the on-site WordPress chatbot are that surface. Visitors ask. You answer from copy you wrote, not from whatever a third-party agent managed to fetch before September 15.
That is not a Cloudflare setting, and we do not change yours. It is the layer that still works if you block Agent, and still works if you let Agent in. For the wider picture of how assistants talk about you when they can see the page, we wrote up AI visibility separately.
Three weeks. Go look at the toggle. Then decide, on purpose, who gets to read the site.